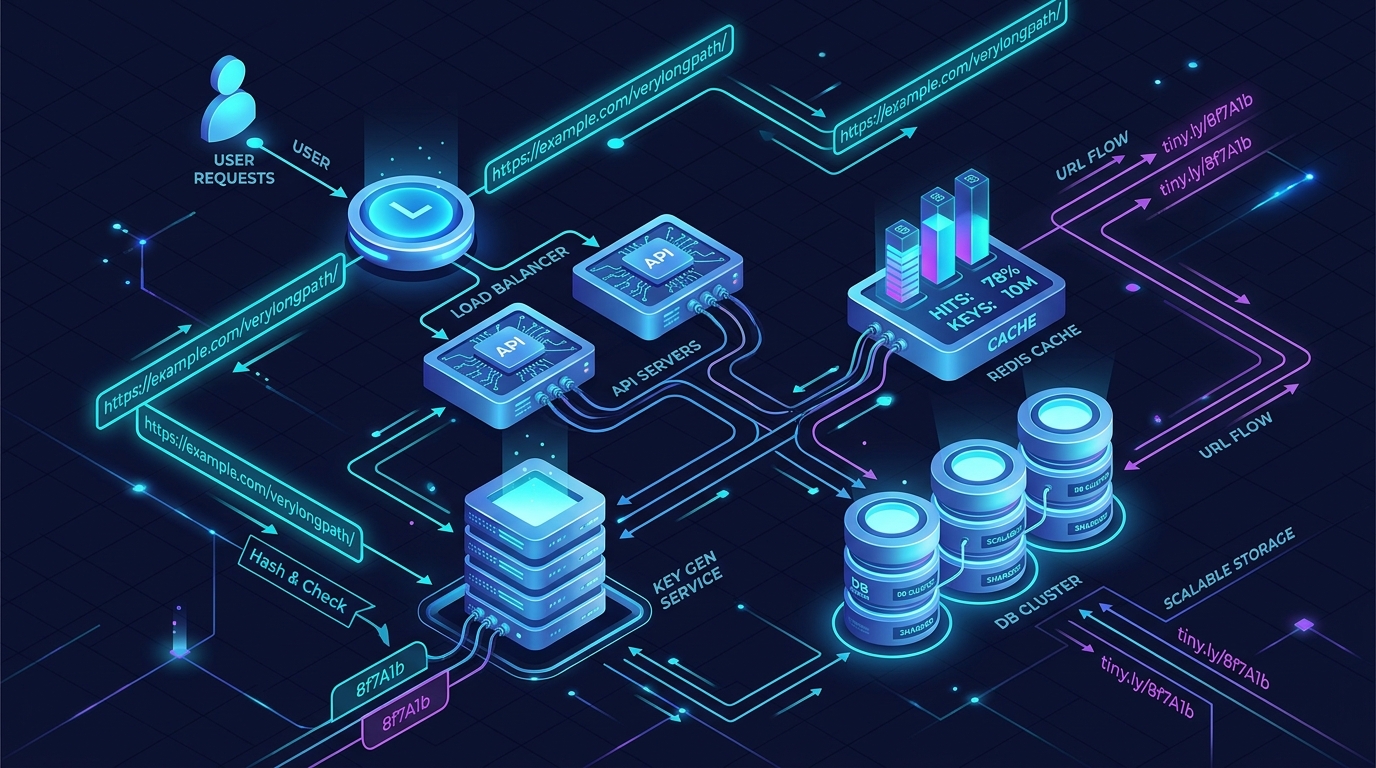
In our foundational guide, The Complete System Design Roadmap, we outlined the five phases of mastering distributed software systems: Networking Foundations, Data & Storage, Distributed Communication, Scale & Reliability, and Interview Execution. Once you grasp the core theory, the very best way to cement your intuition is to design an end-to-end production architecture for a classic real-world problem.
Among all software architecture problems, Designing a Scalable URL Shortener (like TinyURL, Bitly, or Dub.co) is arguably the most famous and instructive question ever asked in engineering interviews at Google, Meta, Amazon, and Stripe. On the surface, the problem sounds deceptively trivial: take a long URL, produce a 7-character string, and redirect users who click it. Yet when you examine the requirements at modern internet scale—handling hundreds of millions of new URLs monthly, billions of redirects, sub-15ms redirection latencies, global high availability, and analytics tracking—you encounter almost every fundamental architectural trade-off in distributed computing.
In this comprehensive, step-by-step guide, we will design a URL shortening system from the ground up. We will cover requirements gathering, back-of-the-envelope capacity estimations, API contracts, hashing algorithms versus distributed token generators (KGS), SQL versus NoSQL storage models, Redis caching, database sharding, and edge-case mitigations like cache stampedes and malicious link abuse.
- 1. Problem Statement & Real-World Context
- 2. System Requirements (Functional & Non-Functional)
- 3. Back-of-the-Envelope Capacity Estimations
- 4. REST API Interface & HTTP Redirect Semantics
- 5. URL Encoding & Short Key Generation Strategies
- 6. Data Storage & Database Schema Design
- 7. High-Level Architecture & Request Flows
- 8. Distributed Caching & Eviction Strategy
- 9. Database Partitioning & High Availability
- 10. Telemetry & Asynchronous Click Analytics
- 11. Security, Rate Limiting & Edge Cases
- 12. Interview Defense Checklist & Trade-offs
- 13. Frequently Asked Questions (FAQ)
- 14. Conclusion & Next Steps
1. Problem Statement & Real-World Context
A URL Shortener takes an arbitrary, lengthy web address (such as https://blog.dhirajroy.com/post/spring-boot-postgresql-crud-jpa-hibernate?ref=twitter&campaign=summer26) and converts it into a concise, compact alias (e.g., https://tiny.ly/8f7A1b). When a visitor accesses the short link, the service immediately resolves the identifier and redirects the user's browser to the destination.
Beyond simply saving characters on SMS and social platforms, production shorteners serve several vital business purposes:
- Link Aesthetics & Cleanliness: Long tracking URLs are unwieldy, visually cluttered, and prone to line-wrapping truncation in messaging channels.
- Branded Domains & Masking: Enterprises use custom branded domains (such as
git.iooramzn.to) to maintain brand recognition and trust. - Marketing & Campaign Attribution: Redirect services capture referrer headers, device fingerprints, geographic regions, and timestamps before dispatching the user, giving marketing teams rich attribution metrics.
- Link Retargeting & Dynamic Routing: The underlying destination URL can be updated dynamically in the database without altering the published short link on physical flyers, print QR codes, or billboards.
2. System Requirements (Functional & Non-Functional)
In any architectural interview or production RFC, never begin drawing database tables or servers until you establish clear functional and non-functional boundaries.
Functional Requirements (What the system MUST do)
- Shorten URL: Given a valid original URL, the system must generate a unique, compact short link (e.g.,
https://tiny.ly/8f7A1b). - Redirection: When a user navigates to a short link, the system must resolve it and redirect them to the original destination with negligible delay.
- Custom Aliases (Optional / Premium): Users should have the option to specify custom vanity aliases (e.g.,
https://tiny.ly/system-design) if available. - Configurable Expiration: URLs can have an optional expiration date (Time-To-Live). Once expired, the link should return an HTTP 404 or 410 Gone.
- Analytics & Metrics: Track basic interaction telemetry (total clicks, referrers, country of origin, and browser agent) for each short link.
Non-Functional Requirements (System qualities & constraints)
- Ultra-High Availability (99.99%): The redirection path is mission-critical. If the redirect server is down, links posted across social media and marketing campaigns fail.
- Ultra-Low Latency: Link resolution and redirection must complete in under 15–20 milliseconds. Users should experience virtually instantaneous redirection.
- Read-Heavy Traffic Asymmetry: The system is vastly read-heavy. There will be roughly 100 reads (redirect clicks) for every 1 write (new URL generated).
- Tamper-Proof & Non-Predictable Keys: Short URLs must not be easily guessable sequentially (e.g.,
/0001,/0002), which would allow attackers to scrape private corporate links. - Fault Tolerance & Scalability: The service must seamlessly scale to billions of stored URLs without degradation in query latency.
3. Back-of-the-Envelope Capacity Estimations
Capacity estimation validates whether our storage, memory, and networking choices will survive real traffic. Let us make reasonable industry assumptions and calculate scale for a 5-year planning horizon.
- New URL Writes: 100 million new URLs created per month (~3.3 million URLs per day).
- Read-to-Write Ratio: 100 : 1.
- Redirection Reads: 10 billion link redirects per month (~330 million redirects per day).
1. Queries Per Second (QPS)
- Write QPS:
$$\text{Daily Writes} = \frac{100{,}000{,}000}{30 \text{ days}} \approx 3{,}333{,}333 \text{ writes/day}$$ $$\text{Write QPS} = \frac{3{,}333{,}333}{86{,}400 \text{ seconds}} \approx \mathbf{38.5 \text{ writes/sec}} \quad (\text{Peak} \approx \mathbf{80 \text{ QPS}})$$ - Read QPS (Redirects):
$$\text{Daily Reads} = \frac{10{,}000{,}000{,}000}{30 \text{ days}} \approx 333{,}333{,}333 \text{ reads/day}$$ $$\text{Read QPS} = \frac{333{,}333{,}333}{86{,}400 \text{ seconds}} \approx \mathbf{3{,}858 \text{ reads/sec}} \quad (\text{Peak } 2\times \approx \mathbf{8{,}000 \text{ QPS}})$$
Key Insight: 40 writes/sec is trivial for any single relational or NoSQL database. However, 4,000 to 8,000 read QPS requires caching and read replicas so the primary database is never saturated.
2. Storage Requirements (5 Years)
Let us estimate the disk space required for each record:
| Field | Data Type | Approximate Size |
|---|---|---|
short_key |
VARCHAR(7) | 7 Bytes |
original_url |
VARCHAR(2048) | ~500 Bytes (average) |
user_id |
UUID / BIGINT | 16 Bytes |
created_at |
TIMESTAMP | 8 Bytes |
expires_at |
TIMESTAMP | 8 Bytes |
| Total per Record | Row + Index Overhead | ~550 Bytes |
- Total Records in 5 Years: $100\text{M} \times 12 \text{ months} \times 5 \text{ years} = \mathbf{6 \text{ Billion Records}}$.
- Total Storage: $6\text{ Billion} \times 550 \text{ Bytes} \approx \mathbf{3.3 \text{ Terabytes}}$.
Conclusion: 3.3 TB across 5 years is surprisingly manageable. A modern SSD RAID array or single distributed database cluster can easily store this volume.
3. Memory & Cache Requirements (The 80/20 Rule)
According to the Pareto Principle (80/20 rule), roughly 20% of your URLs generate 80% of all redirect traffic (viral posts, homepage links, breaking news). By caching this hot 20% in an in-memory cache like Redis, we can serve 80%+ of read requests directly from RAM in less than 2 milliseconds.
- Daily Redirect Volume: ~330 Million requests per day.
- 20% Hot Working Set: $330\text{M} \times 0.20 = 66\text{ Million URLs/day}$.
- Cache Memory Needed: $66\text{ Million} \times 550 \text{ Bytes} \approx \mathbf{36.3 \text{ Gigabytes RAM}}$.
36 GB of RAM is easily accommodated on a modest two-node Redis cluster with high availability replication.
4. REST API Interface & HTTP Redirect Semantics
Our API layer provides clear, stateless endpoints adhering to standard HTTP semantics.
Endpoint 1: Create Short URL
POST /api/v1/shorten
Content-Type: application/json
Authorization: Bearer <api_token>

{
  "original_url": "https://blog.dhirajroy.com/post/system-design-roadmap-beginner-to-advanced",
  "custom_alias": "sys-roadmap",  // Optional vanity alias
  "expires_in_days": 365            // Optional TTL
}
Response (HTTP 201 Created):
{
  "short_url": "https://tiny.ly/sys-roadmap",
  "short_key": "sys-roadmap",
  "original_url": "https://blog.dhirajroy.com/post/system-design-roadmap-beginner-to-advanced",
  "created_at": "2026-09-21T10:00:00Z",
  "expires_at": "2027-09-21T10:00:00Z"
}
Endpoint 2: Redirect Short URL
GET /{shortKey}
Host: tiny.ly
Response: Redirection status code (see below) with the Location header pointing to the destination URL.
The Redirection Dilemma: HTTP 301 vs HTTP 302/307
One of the most frequent senior interview questions is choosing between 301 Permanent Redirect and 302/307 Temporary Redirect. Let us evaluate the exact trade-offs:
| Redirect Code | Browser Behavior | Server Load | Analytics & Click Tracking |
|---|---|---|---|
| 301 Moved Permanently | Browser aggressively caches the target URL in local disk cache. Future clicks bypass our server completely. | Extremely Low (subsequent hits never reach our server). | ❌ Poor. You miss repeat clicks and cannot track user interactions accurately. |
| 302 Found / 307 Temporary | Browser does not cache permanently; every subsequent click sends an HTTP GET request to our server. | Higher (every single click hits our edge/caching tier). | ✅ Excellent. Every click is intercepted, recorded, and analyzed for marketing attribution. |
Architectural Decision: If monetization and analytics tracking are core business requirements (as with Bitly and enterprise shorteners), use HTTP 302 (or 307). If server cost minimization is paramount and analytics are irrelevant, use HTTP 301.
5. URL Encoding & Short Key Generation Strategies
How do we turn an arbitrary URL into a concise, unique 7-character string without collisions or performance bottlenecks? Let us analyze the mathematics and engineering options.
Why Base62? The Math of Key Length
A standard URL key consists of alphanumeric characters:
- Lowercase letters:
a-z(26 characters) - Uppercase letters:
A-Z(26 characters) - Numeric digits:
0-9(10 characters) - Total Characters: $26 + 26 + 10 = \mathbf{62 \text{ characters (Base62)}}$.
Unlike Base64 (which includes +, /, or = padding that requires URL percent-encoding), Base62 is 100% URL-safe out of the box.
How many unique links can we represent with different key lengths?
- Length 6: $62^6 \approx \mathbf{56.8 \text{ Billion unique URLs}}$
- Length 7: $62^7 \approx \mathbf{3.52 \text{ Trillion unique URLs}}$
- Length 8: $62^8 \approx \mathbf{218 \text{ Trillion unique URLs}}$
At 100 million URLs per month, our 5-year requirement is only 6 billion URLs. A 7-character Base62 string provides 3.52 Trillion combinations—enough capacity to run for thousands of years without exhausting the address space!
Strategy A: Hashing (MD5 / SHA-256) + Base62 Truncation
One intuitive approach is hashing the original URL:
- Compute the MD5 hash of
original_url, producing a 128-bit hash (32 hexadecimal characters). - Encode the hash into Base62 and take the first 7 characters.
The Critical Flaw: Hash Collisions!
Because MD5 produces 128 bits and we truncate to just 7 characters (~42 bits of entropy), collisions are mathematically guaranteed under the Birthday Paradox. If two different URLs produce the same 7-character prefix, the system must append a salt or incremental counter (e.g., original_url + salt) and re-hash until a non-conflicting key is found. This requires iterative database checks, adding latency and contention to every write.
Strategy B (Production Standard): Distributed Key Generation Service (KGS)
Instead of calculating hashes at request time, what if the system generates unique keys ahead of time?
How the Key Generation Service (KGS) Works:
- A standalone background process generates random, non-sequential 7-character Base62 strings offline and inserts them into a
key_pooltable. - The table has two states:
USED = 0(available) andUSED = 1(allocated). - When the KGS server boots up, it loads a block of keys (e.g., 10,000 keys) into fast server memory and immediately marks them as allocated in the backing database.
- When application servers need a new short key, they make a blazing-fast in-memory RPC call to the KGS. The key is returned in under 0.5 milliseconds with guaranteed uniqueness and zero collision checks!
What happens if the KGS server crashes?
If a KGS instance holding 10,000 cached keys crashes, those 10,000 keys are simply lost. Because our 7-character space contains 3.52 Trillion keys, losing a few thousand keys is completely inconsequential and does not impact data integrity.
Alternative to KGS: Distributed Range Counter (Snowflake / ZooKeeper)
Another popular production approach uses an atomic distributed counter:
- A coordination service like Apache ZooKeeper or a Redis cluster assigns integer ID ranges to each API worker instance (e.g., Worker 1 gets
1,000,000 – 1,999,999, Worker 2 gets2,000,000 – 2,999,999). - Each worker increments its internal counter locally and converts that 64-bit integer into Base62.
- Example: The integer
11,157,105converted to Base62 becomes"8f7A1b". - To prevent sequential guessing attacks, workers apply a reversible bitwise shuffle/permutation algorithm before converting to Base62.
6. Data Storage & Database Schema Design
Relational (SQL) vs NoSQL Comparison
| Architecture Trait | Relational (PostgreSQL / MySQL) | NoSQL Key-Value (DynamoDB / Cassandra) |
|---|---|---|
| Data Model | Structured tables with foreign keys and relational schemas. | Simple primary key -> JSON document or byte payload. |
| Relational Joins | Supported (though unnecessary for basic short URL lookup). | None required. |
| Horizontal Scaling | Requires manual sharding, connection pooling, and replication lag handling. | Auto-shards natively across clusters based on partition hash key. |
| Ideal Fit | Great if you already have existing relational infrastructure and strict ACID billing needs. | Optimal for high-throughput URL lookup (Cassandra, DynamoDB, MongoDB). |
PostgreSQL Database Schema
If implemented in PostgreSQL, the table definition is straightforward and highly index-optimized:
CREATE TABLE urls (
    short_key     VARCHAR(16) PRIMARY KEY,
    original_url  VARCHAR(2048) NOT NULL,
    user_id       BIGINT,
    created_at    TIMESTAMP WITH TIME ZONE DEFAULT CURRENT_TIMESTAMP NOT NULL,
    expires_at    TIMESTAMP WITH TIME ZONE,
    click_count   BIGINT DEFAULT 0 NOT NULL
);

-- B-Tree Index on short_key is automatically created by the PRIMARY KEY constraint.
-- Optional index for user dashboard queries:
CREATE INDEX idx_urls_user_id ON urls(user_id);

-- Optional index for background expiration sweeps:
CREATE INDEX idx_urls_expires_at ON urls(expires_at) WHERE expires_at IS NOT NULL;
7. High-Level Architecture & Request Flows
Now let us assemble all distributed components into a unified, high-availability architecture diagram.
End-to-End Request Flows
1. Write Flow (Creating a Short URL)
- The client sends a
POST /api/v1/shortenrequest containing the original long URL. - The Load Balancer terminates TLS and routes the request to an available stateless API server.
- The API server validates the URL format, sanitizes parameters, and verifies client rate limits.
- If a custom alias is requested, the server checks the database/cache for existence. If none was specified, the server fetches an unused 7-character key from the Key Generation Service (KGS) in local memory.
- The server writes the
(short_key, original_url, user_id, expires_at)record to the primary database. - The server pre-populates the key in the Redis Cache with an appropriate TTL to prepare for immediate sharing.
- The server returns the full shortened URL payload (HTTP 201 Created) to the client.
2. Read Flow (Redirecting a Short URL)
- A user clicks
https://tiny.ly/8f7A1bin their browser. - The request passes through GeoDNS and hits the closest Edge Load Balancer.
- The API server inspects Redis Cache for the key
"url:8f7A1b". - Cache Hit (90%+ of queries): Redis returns the original URL in ~1ms.
- Cache Miss: The API server queries the Database Read Replica, populates Redis with the result, and continues.
- If the link does not exist (or has expired), return an HTTP 404 Not Found.
- The server asynchronously publishes a
LinkClickEventmessage to an Apache Kafka topic. - The server responds immediately to the user with an HTTP 302 Found redirect header:
Location: https://blog.dhirajroy.com/.... The user's browser redirects instantaneously!
8. Distributed Caching & Eviction Strategy
Because link redirection is intensely read-heavy, performance lives and dies by the caching tier.
Cache Pattern: Cache-Aside (Lazy Loading)
We implement the Cache-Aside pattern:
- Application checks Redis for the key.
- If present, return immediately (Cache Hit).
- If absent, read from database, write value into Redis, and return (Cache Miss).
Cache Eviction Policy: LRU
When Redis reaches its maximum memory threshold (e.g., 32 GB), it must evict entries. We configure the AllKeys-LRU (Least Recently Used) policy. Links that have stopped receiving clicks naturally drop out of memory, while viral links remain pinned in RAM.
Mitigating Cache Stampede & Cache Penetration
- Cache Stampede: If a viral celebrity link with 10,000 QPS expires from cache, thousands of concurrent requests could strike the database simultaneously. We mitigate this using Mutual Exclusion Locks (Redis Mutex) or probabilistic early expiration (XFetch algorithm).
- Cache Penetration: Malicious bots frequently query non-existent keys (e.g.,
tiny.ly/fakeKey99). If unhandled, every request hits the database. We protect against this by placing a Bloom Filter in front of the cache or caching emptynullvalues with a short 60-second TTL.
9. Database Partitioning & High Availability
While 3.3 TB can fit on a modern disk, distributing storage across multiple nodes ensures we never exceed single-machine I/O limits and guarantees zero downtime during hardware maintenance.
Sharding by Hash of Short Key
We partition data horizontally across database shards using Consistent Hashing on the short_key:
This guarantees an even distribution of records across all database nodes and prevents "hot spots" where one server receives 90% of write traffic.
Leader-Follower Replication
Each database shard is configured with one Primary Leader (for writes) and two Asynchronous Read Replicas (for reads). If the primary node fails, automatic failover (via Patroni or AWS Aurora Multi-AZ) promotes a replica to leader within seconds.
10. Telemetry & Asynchronous Click Analytics
Updating a click counter synchronously in the primary database during the redirect request is an architectural anti-pattern. Doing a database write on every single redirect adds disk I/O, creates table row-lock contention, and inflates redirect latency from 10ms to 100ms+.
- When a redirect occurs, the API server emits an asynchronous JSON event to a distributed log stream (e.g., Apache Kafka or RabbitMQ):
{ "short_key": "8f7A1b", "timestamp": "2026-09-21T10:15:32Z", "referrer": "https://t.co/", "user_agent": "Mozilla/5.0 (iPhone; CPU iPhone OS 17...)", "ip_address": "203.0.113.42", "geo_country": "US" } - A pool of decoupled stream consumers (written in Go or Java) reads events in micro-batches (e.g., every 5 seconds or 1,000 events).
- The consumers aggregate counts and flush analytics data into an OLAP columnar database designed for time-series aggregation, such as ClickHouse, Apache Pinot, or AWS Timestream.
- The user's analytical dashboard queries ClickHouse without placing any load on the operational redirect database.
11. Security, Rate Limiting & Edge Cases
1. Malicious Link Abuse & Phishing
URL shorteners are notorious targets for spammers attempting to disguise phishing domains or malware downloads. To protect users and preserve domain reputation:
- During link creation, asynchronously query the Google Safe Browsing API to verify the destination host against active blacklists.
- Maintain an internal blacklist of forbidden domains and malware URL patterns.
- Present an interstitial warning screen for unverified accounts before redirection if suspicious parameters are detected.
2. Distributed Rate Limiting
To prevent malicious bots from exhausting the key space or launching denial-of-service attacks, place a distributed rate limiter at the API gateway tier:
- Implement the Token Bucket or Sliding Window Log algorithm in Redis.
- Enforce quotas: e.g., max 10 URL creations per minute per IP address, or 500 requests per minute for authenticated API token tiers.
- Excessive requests are rejected immediately with HTTP 429 Too Many Requests without touching downstream services.
3. Link Expiration & Garbage Collection
How do we clean up billions of expired URLs without slowing down active traffic?
- Lazy Deletion: When a user navigates to an expired link, the application detects that
expires_at < NOW(), deletes the key from Redis, and returns an HTTP 410 Gone. No expensive background sweeps are required for rarely accessed links. - Scheduled Low-Priority Batch Purge: During off-peak hours (e.g., 03:00 UTC), a background cron worker performs chunked deletions:
DELETE FROM urls WHERE expires_at < NOW() LIMIT 5000;
12. Interview Defense Checklist & Trade-offs
When presenting this design in a 45-minute technical interview, interviewers evaluate how fluently you justify your choices. Use this mental matrix to defend your architecture:
| Decision Point | Your Recommended Choice | Architectural Justification |
|---|---|---|
| Encoding Method | Key Generation Service (KGS) or Counter + Base62 | Guarantees unique keys with zero collision checks and sub-millisecond generation speed. |
| Redirect Code | HTTP 302 Found (or 307) | Prevents browser-level permanent caching, enabling full click telemetry and fraud detection. |
| Caching Tier | Redis Cluster (Cache-Aside + LRU) | Stores top 20% hot links in RAM (~36 GB), fulfilling 80%+ reads under 2ms. |
| Database | NoSQL (Cassandra/DynamoDB) or Sharded Postgres | Simple key-value lookup semantics, seamless horizontal scaling across partitions. |
| Click Analytics | Asynchronous Kafka + ClickHouse | Decouples analytics writes completely from the critical user redirect latency path. |
13. Frequently Asked Questions (FAQ)
What is the difference between HTTP 301 and HTTP 302 redirects in a URL shortener?
HTTP 301 (Moved Permanently) instructs web browsers to cache the target URL on disk, completely bypassing the shortener server on all subsequent clicks. While this reduces server compute costs, it prevents you from recording real-time analytics. HTTP 302 (Found) or 307 (Temporary Redirect) ensures every user interaction hits your server, allowing comprehensive analytics tracking.
Why is Base62 used instead of Base64 or Hexadecimal for short URLs?
Base62 uses alphanumeric characters [0-9, a-z, A-Z], which are inherently URL-safe without escaping. Base64 introduces special symbols like + and /, which can break in URL routing or query parameters. Hexadecimal (Base16) uses only 16 symbols, requiring much longer strings to represent the same number of keys.
How does a Key Generation Service (KGS) prevent duplicate keys and race conditions?
A Key Generation Service pre-generates unique Base62 tokens offline and maintains them in a persistent data store. Standalone KGS servers load non-overlapping blocks of tokens into local memory using an atomic coordinator (like Apache ZooKeeper or Redis INCR). When an application worker requests a key, KGS hands one over instantaneously with zero collision risk and zero runtime hashing computation.
Should we choose a Relational (SQL) or NoSQL database for a URL shortener?
Both can work effectively, but NoSQL distributed key-value stores (such as DynamoDB, Cassandra, or ScyllaDB) naturally align with this workload because records are simple key-value pairs (short_key -> original_url), there are no complex relational joins, and NoSQL horizontally partitions across multiple nodes without manual sharding logic.
14. Conclusion & Next Steps
Designing a scalable URL shortener is a masterclass in distributed engineering trade-offs. What begins as a simple link-forwarding service quickly demands deep consideration of encoding mathematics, database sharding, in-memory caching strategies, and asynchronous stream processing.
By stepping methodically through functional requirements, back-of-the-envelope calculations, and architectural trade-offs, you demonstrate the mindset of a senior engineer—building software that remains lightning-fast, resilient, and cost-effective under relentless real-world traffic.
Where to go next: To continue your system design journey, explore our foundational guide on The Complete System Design Roadmap or dive into backend security with our guides on API Rate Limiting in Node.js and Docker from Zero to Production.